
API Regression Testing: Strategy, Automation and CI/CD
Quick answer
API regression testing re-runs an API test suite after every change to prove that behaviour which worked before still works. Generate the baseline from the OpenAPI spec, add business-rule tests by hand, run a fast set on every pull request and the full suite on merge, and gate merges on the result so regressions are caught in minutes.
Reviewed by Smeet Gohel
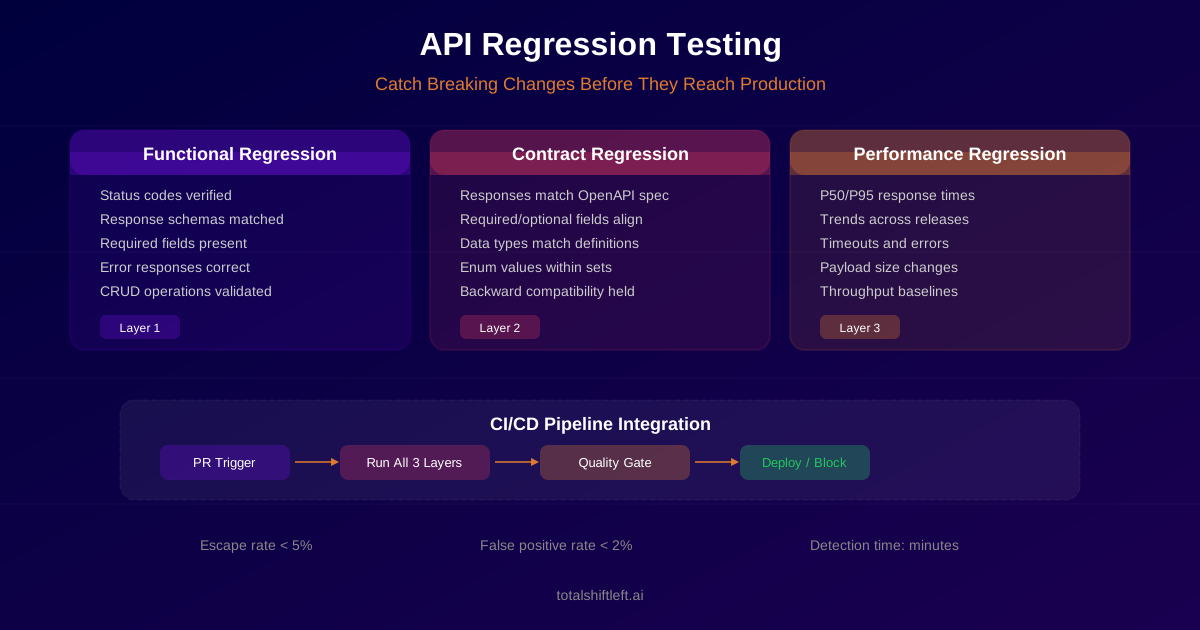
API regression testing is the automated discipline of re-running a curated suite of functional, contract, and performance tests after every code change to prove that previously working API behavior still works. It replaces late-stage manual validation with continuous, pipeline-enforced checks that catch unintended side effects — a fix in orders breaking inventory, a renamed field crashing mobile clients, a query rewrite multiplying latency tenfold — at pull-request time rather than in production.
This guide is one of the two pillars of our API testing in CI/CD hub; the other, API testing in CI/CD, covers the pipeline wiring. If you are evaluating a platform rather than a practice, see automated API regression testing. Regression testing is no longer a QA phase; it is the mechanism that lets API teams ship at weekly or daily cadence without breaking the consumers that depend on them.
Every team that ships API changes quickly encounters the same fear: did this update break something that was already working? A bug fix in the orders service silently breaks the inventory endpoint because they share a database query. A new required field causes every mobile client to crash. A "small" performance optimization turns a 200ms endpoint into a 2-second timeout under load. These are regressions — unintended side effects of intentional changes — and they are by a wide margin the dominant source of production API incidents.
The cure is not more manual QA or bigger staging environments. It is a disciplined, automated regression testing strategy wired into CI/CD so that every commit is proven safe before it merges. This guide covers what regression testing is, the kinds of regression a suite has to catch, the reference architecture, tooling, how AI changes the maintenance work, common failure modes, and the metrics worth tracking. For fundamentals, our API Learning Center covers what an API is and request/response anatomy.
In this guide
- What Is API Regression Testing?
- Why API regression testing matters in 2026
- Key Components of API Regression Testing
- API regression testing reference architecture
- API regression testing tools compared
- What AI changes in a regression suite
- API regression testing in practice: a worked example
- API regression testing challenges and how to solve them
- API regression testing best practices
- API regression testing checklist
- Catch the regression before the tests even run
- API regression testing FAQ
What Is API Regression Testing?
API regression testing verifies that changes to your codebase have not broken existing API behavior. Every time code is pushed — a bug fix, a new feature, a dependency bump, a configuration change, a refactor — the regression suite re-runs to confirm that previously working endpoints still return correct status codes, responses still match the committed schema, authentication still succeeds, and latency is still within baseline.
The distinction from one-time functional testing is important but subtle. The same test case that validated a feature during development becomes a regression test the moment it enters the automated suite. The test itself does not change — what changes is the cadence and intent. Functional testing asks "does this new behavior work?" Regression testing asks "does everything that used to work still work?" The former is bounded and done; the latter runs forever, on every change, until the endpoint is deprecated.
Without it, teams discover regressions through the most expensive channel possible: production incidents reported by real users. A field that used to be a string is now an integer. A 200 response is now a 500. A filter parameter that narrowed results now returns everything. These are exactly the categories of failure that a well-designed regression suite catches hours or days before production — typically within the four-to-seven minutes it takes a CI pipeline to finish. See API schema validation: catching drift for how schema-level regressions escape without automation.
Regression testing is often confused with smoke testing, and the two need different suites: a smoke set answers "is this deployment alive?" in a minute or two, while the regression suite answers "did anything that used to work stop working?". The difference, and where each runs in the pipeline, is set out in smoke testing vs regression testing.
Why API regression testing matters in 2026
Microservice sprawl outpaces manual regression coverage
Mid-sized platforms commonly run dozens to hundreds of internal services, each with its own API surface and release cadence. Hand-authoring and hand-maintaining regression tests for that surface does not scale: if a test takes half an hour to write and a few minutes a month to maintain, a few thousand tests absorb several engineers full-time. Automation is not a nice-to-have; it is the only model that scales. See API test automation with CI/CD step by step for concrete wiring.
Release cadence has compressed past traditional QA cycles
Teams that deploy several times a day cannot wait for a QA sign-off. A 48-hour sign-off cycle either blocks those releases or gets skipped — and once it gets skipped, the regression safety net is gone. Running the full suite inside the pull request is the only pattern that sustains weekly-or-faster cadence without regression escape.
Consumer-side breakage cascades are the hidden cost
APIs do not fail in isolation. A broken response schema becomes a broken mobile app, a broken partner integration, a broken internal microservice, and — increasingly — a broken AI agent that parses your API output. A single silent regression in a core service can generate dozens of incidents across dependent teams. Contract testing enforced as part of every regression cycle is the only systematic defense.
Independent deployment requires automated protection
The promise of microservices is independent deployment. Without regression testing, teams fear breaking consumers and quietly revert to coordinated releases, shared deployment windows, and manual compatibility checks — the very bottlenecks microservices were meant to eliminate. See best API testing tools.
AI consumers magnify the cost of contract breakage
Generative AI agents calling your APIs cannot gracefully recover from undocumented schema changes the way a human operator can. A single extra field or renamed property can derail an entire agent workflow. This makes 2026 the year regression testing stops being a "QA concern" and becomes a platform-reliability concern.
Key Components of API Regression Testing
Functional regression
Re-runs existing functional tests — positive paths, happy-path CRUD flows, and known-good business logic — on every code change to catch outright breakage in what used to work. This is the foundation layer. If you only implement one layer, make it this one. See test execution for how parallel execution keeps functional regression feedback fast.
Contract regression
Validates that every response still conforms to the committed OpenAPI specification. Catches silent schema drift — a type change, a removed field, a new required property — that functional tests miss because the response still "looks right." Platforms like Shift-Left API validate every response against the spec automatically. Deeper reading: what is API contract testing and contract testing in the Learn hub.
Performance regression
Tracks P50, P95, and P99 response times per endpoint and flags degradations beyond a defined threshold (typically 150% of baseline). Catches the category of bug where the response is structurally correct but takes 30 seconds instead of 300 milliseconds — the slowest common regression type to detect manually.
The hard part is telling a real slowdown from normal variation. Shift-Left API's performance and load testing — a paid add-on that the Trial includes — builds load tests from the functional regression tests you already have, then compares each run against a pinned baseline with a statistical test over p95 rather than a fixed percentage, so ordinary noise is not reported as a regression. Performance targets can also be judged on ordinary functional runs, which puts a latency check into every regression cycle, not only the load runs; targets linked to requirements show as met or missed in the traceability matrix's Under load column.
Negative-path regression
Re-runs tests for error cases: 400 on malformed input, 401 on missing auth, 403 on insufficient permissions, 404 on nonexistent resources, 422 on validation failure. A surprising number of production incidents involve error handlers that used to return clean 4xx responses and silently started returning 500s after a refactor. See AI-assisted negative testing for generation patterns.
Coverage regression
A new endpoint ships without tests, or a new status code appears that nothing asserts. Nothing "fails", yet the safety net just got thinner. Treat coverage as a regression class of its own: compare the suite against the spec on every run, and make an uncovered new operation either get tests or get a documented exception. Shift-Left API's coverage dashboard shows the endpoints and requirements that have no tests.
Behavioural (business-rule) regression
The endpoint returns a valid, schema-compliant response, but the behaviour is wrong: a discount endpoint returns 200 and does not apply the discount. Schema checks can never catch this; it needs tests derived from the business rule. In Shift-Left API those rules can come from requirement documents (Excel workbooks, user stories from Jira or Azure DevOps, Gherkin) with boundary-value, equivalence-class and decision-table cases generated per rule, and the traceability matrix shows which requirements still lack a test.
Authentication and authorization regression
Re-verifies that token flows, scope checks, role-based permissions, and expiry handling still behave as expected. Auth regressions are among the highest-severity failure classes because they can silently either grant too much access or lock out legitimate users. The "grants too much" direction is the one functional suites rarely test, because it needs a second identity; Shift-Left API's security testing add-on (also paid, included in the Trial) checks it in your packs, schedules and CI runs with a second test user and an access matrix of Deny, Own data only or Allow per endpoint. Deeper coverage: JWT authentication, OAuth2 client credentials, and token refresh patterns.
Change detection and spec diffing
Computes a structural diff between the previous and current OpenAPI specs and between the spec and the running service. Classifies changes as additive (new optional field), breaking (removed field, type change, tightened required semantics), or ambiguous. This is the input that drives change review and breaking-change alerts.
Ready to shift left with your API testing?
Try our no-code API test automation platform free. Generate tests from OpenAPI, run in CI/CD, and scale quality.
Reviewed maintenance layer
Each change to a re-imported spec is classified as breaking or non-breaking, so additive changes such as new optional fields, extended enums and added endpoints are queued for approval, while removed capability and changed required semantics always need review. Without this layer, maintenance cost grows linearly with the rate of API change. See self-healing API tests: how they work and AI test maintenance.
How automatic "automatically" should be is a policy choice. Shift-Left API does not rewrite tests when the spec changes: a re-imported spec is diffed, each change is classified as breaking or non-breaking, and approved changes become new endpoint versions. Repair happens after a test fails, and it is always a proposal that cites its evidence (spec, requirement, run) and waits for a person to accept it. It never loosens a test and refuses to edit a test to match a product bug — which is the one "heal" that turns a regression suite into a regression-hiding suite.
CI/CD quality gates and reporting
The enforcement surface: pull-request annotations, merge blocks, deploy blocks, Slack/Teams escalations, JUnit XML / SARIF output, and historical trend dashboards. Without gates, the suite is advisory and gets ignored. See API testing in CI/CD and analytics and monitoring.
API regression testing reference architecture
A production-grade API regression testing system is best understood as five collaborating layers.
Layer 1 — the source-of-truth layer holds the committed OpenAPI specification, the live running service, and the authentication configuration. A change to any of these is the trigger event: a spec commit, a service deploy, a secret rotation, or a pull request modifying the implementation. The spec is versioned in the same repository as the application code to keep them in lock-step.
Layer 2 — the generation and change-detection layer parses the spec, compares it against the previous revision and against live-service introspection, and produces a ranked diff. From that diff it generates or updates the regression suite: positive, negative, contract, and boundary cases. It stores the resulting suite keyed to the spec hash, so every run is reproducible and attributable. This layer is where a true AI-first platform differs from scripted tooling — it generates rather than requires humans to author.
Layer 3 — the execution layer runs the suite against target environments in parallel shards. It resolves auth, issues requests, captures responses, evaluates assertions against both the spec and learned performance baselines, and emits structured results. Execution is headless, deterministic, and designed to complete within the budget a pull request can tolerate (typically under five minutes). This is where API protocol support — REST, GraphQL, SOAP, JSON-RPC, WebSocket — needs to be first-class.
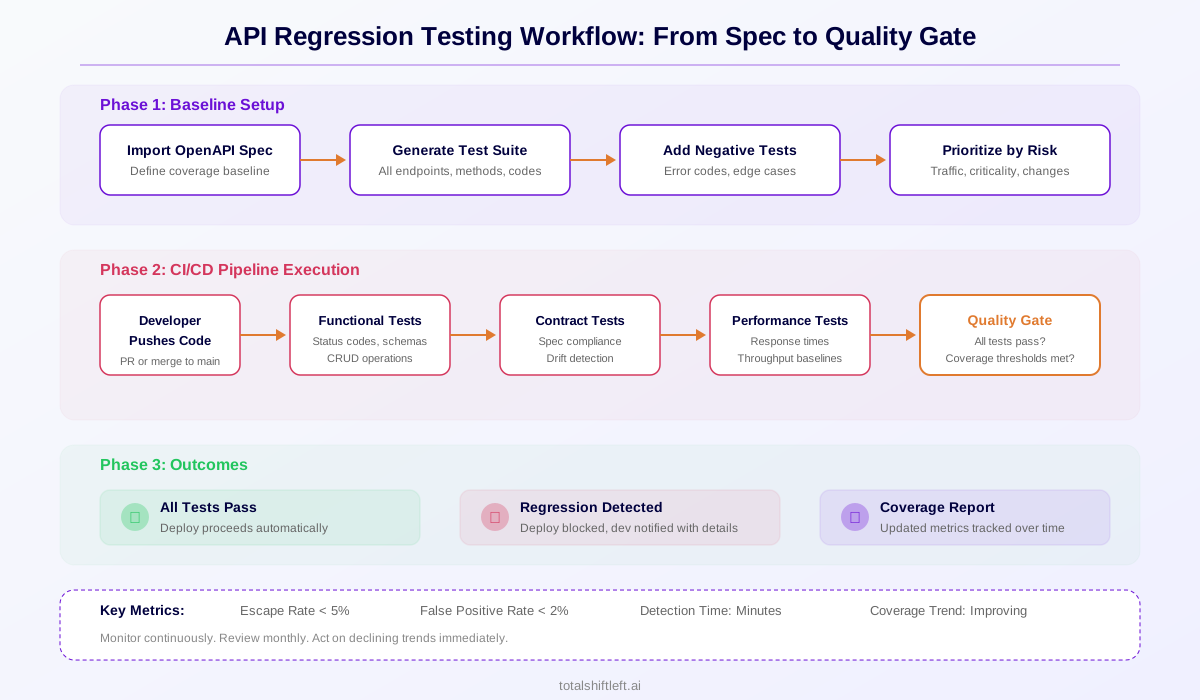
Layer 4 — the gating and feedback layer surfaces results where developers work: PR annotations, inline diffs of expected-vs-actual responses, historical flakiness scores, one-click local reproduction, Slack/Teams escalation, and merge blocks. This layer determines adoption more than any other. A brilliant generation engine with poor feedback UX gets abandoned; a merely adequate engine with excellent feedback becomes the team's safety net.
Layer 5 — the governance layer cross-cuts everything: secrets management, RBAC, audit logging, environment isolation, compliance controls (SOC 2, ISO 27001, HIPAA where relevant), and retention policies for historical runs. See collaboration and security for enterprise patterns. The governance layer is what distinguishes a hobbyist tool from a platform that can be trusted with production-bound validation.
API regression testing tools compared
| Platform | Approach | Regression Strength | CI/CD Integration | Best For |
|---|---|---|---|---|
| Shift-Left API | AI-first, spec-driven, AI repair of failing tests with review | Functional + contract with auto-generation; performance via load-testing add-on | First-party GitHub Actions, Jenkins, Azure DevOps; REST API for GitLab, CircleCI and others | Teams wanting full regression automation without manual authoring |
| Postman + Newman | Collection-based, manual | Functional only; manual maintenance | Newman CLI in any pipeline | Teams with existing Postman investment migrating gradually |
| ReadyAPI (SmartBear) | Scripted, enterprise | Functional + load regression | Jenkins, Azure DevOps | Enterprise SOAP/REST with heavy legacy protocol needs |
| REST Assured | Java library, code-first | Functional, developer-owned | Maven/Gradle, any CI | Java teams embedding regression in unit-test infrastructure |
| Karate | DSL-based BDD | Functional + contract via Gherkin | Maven, any CI | Teams wanting readable DSL and shared product/QA ownership |
| Schemathesis | Property-based fuzzing | Contract + edge-case regression | CLI in any CI | Engineers wanting spec-driven fuzzing alongside curated tests |
| Apidog | Design + test hybrid | Functional with basic contract | Lightweight CI hooks | Small-to-mid teams standardizing spec-first |
| Supertest | Node.js library | Functional, per-service | npm scripts, any CI | Node.js teams embedding regression in service test suites |
Deeper comparisons: top OpenAPI testing tools compared, best Postman alternatives, and side-by-side breakdowns in the Learn hub: ReadyAPI vs Shift Left, Apidog vs Shift Left, and best AI API testing tools 2026. For teams wanting the shortest path from OpenAPI to a comprehensive regression suite, Shift-Left API's regression testing product generates the suite automatically, flags spec changes for approval at import, and proposes repairs for failing tests that your team reviews.
What AI changes in a regression suite
Generation is the part vendors demonstrate; maintenance is the part that decides whether the suite is still running in a year. The useful question when evaluating any AI or spec-driven tool is the last column of this table:
| Stage | Traditional | With AI or spec-driven generation | What still needs a human |
|---|---|---|---|
| Authoring cases | Hand-written per endpoint | Derived from the spec, including negative and boundary cases | Business rules the schema does not express |
| Test data | Fixtures maintained by hand | Generated from the schema | Deciding what realistic means for your domain |
| Maintenance after a spec change | Every affected test edited | The change is classified and approved, failing tests get proposed repairs | Reviewing the diff and each repair before trusting it |
| Triage of a failure | Read the log, reproduce locally | Failures grouped by cause with a likely verdict | Deciding whether it is a bug or an intended change |
| Flaky test handling | Quarantine and forget | Detected across runs and flagged | Fixing the underlying nondeterminism |
| Coverage tracking | A manual spreadsheet | Computed against the spec on every run | Setting the floor, and enforcing it |
A platform that claims nothing is left to a human is describing a demo, not a regression suite.
Two AI-era practices are worth adopting whatever tool you use. First, pair the API regression suite with a small set of cross-service workflows: a regression that only appears when three services call each other in sequence will not show up in single-endpoint tests. In Shift-Left API those workflows can be built from approved use-case requirements or from the spec and existing tests, with each step's data wired to the step that produces it. Second, inspect green runs, not just red ones: a passing regression test that would not notice the regression it exists for is a false comfort. Shift-Left API's run analysis flags passing tests that assert too little, with suggested checks that only ever add assertions.
API regression testing in practice: a worked example
Illustrative scenario: a composite example, not a named customer's measured results.
Problem: A mid-market e-commerce company operating a 40-endpoint REST API across users, products, orders, payments, and shipping was experiencing an average of two production regressions per month. Their test estate consisted of 60 hand-written Postman collections covering happy paths only. Schema drift between the API and the committed OpenAPI spec had caused three consumer-facing incidents in the prior quarter, including a pricing bug where an integer field briefly serialized as a string and crashed the checkout flow on iOS. QA capacity was consumed almost entirely by triaging production reports and manually updating collections after each release.
Solution: The team adopted a three-phase plan over twelve weeks. In phase one (weeks 1-3) they imported the OpenAPI spec into an AI-first regression platform, which auto-generated 280 test cases covering all 40 endpoints, every HTTP method, success and error statuses, and basic parameter validation. In phase two (weeks 4-7) they layered in 40 hand-authored business-logic tests the spec could not express — order total calculations, inventory deduction, payment authorization, shipping rules — and wired the combined 320-test suite into GitHub Actions as a blocking PR check. They set quality gates at 85% endpoint coverage and 75% status-code coverage, tracked with API test coverage metrics. In phase three (weeks 8-12) they added performance baselines for the 10 highest-traffic endpoints (flagging any P95 exceeding 150% of baseline) and turned on auto-approval for additive, non-breaking spec changes.
Results: In a scenario like this, the CI gate stops most regressions in pull requests, so production regression incidents fall toward zero, and the time to detect a regression moves from days to minutes. QA time that went to triage and manual collection maintenance moves to exploratory testing and performance work. Measure incidents and detection time against your own baseline.
API regression testing challenges and how to solve them
Flaky tests destroy trust in the suite
A regression suite with even a few consistently flaky tests rapidly loses credibility; developers start ignoring failures, and real regressions slip through in the noise. Solution: Treat every flaky test as a P2 bug. Quarantine it immediately, investigate the root cause (timing assumptions, shared mutable state, non-deterministic data), and either fix or delete it. Never "retry until green" as a permanent strategy — that pattern hides real issues. Track flakiness as a first-class KPI alongside pass rate.
It also helps to stop reading a red run test by test. Shift-Left API groups a failed run into a handful of causes — test defect, data issue, environment problem or suspected product bug — based on what the server actually returned, so a gateway error page, an expired sign-in or rate limiting is not mistaken for a regression. Every test sharing a cause can then be fixed in one reviewed step.
Free YAML templates + guide
CI/CD Testing Pipeline Templates
Production-ready CI/CD pipeline templates for GitHub Actions and GitLab CI. Includes API testing, contract testing, and performance testing stages.
Download FreeTest maintenance overhead grows faster than the API
Traditional hand-written regression suites accumulate maintenance debt at the rate the API changes, and the debt grows fastest in high-change environments. Solution: Use spec-driven generation and reviewed repair; see how reviewed AI repair works. Set a change-review policy explicitly: auto-approve additive non-breaking changes, require review on anything affecting required semantics or removing capability. See AI test maintenance.
CI execution time balloons past developer tolerance
A sequential 40-minute regression run is a productivity killer — developers start bypassing the suite or batching PRs to amortize the wait. Solution: Shard aggressively across parallel CI runners (10-way sharding turns 40 minutes into 4). Use smart test selection on feature branches to prioritize tests related to changed code paths, and always run the full suite on merge to main. Budget for under five minutes of PR feedback and treat anything longer as a reliability bug.
False positives from low-quality OpenAPI specs
Specs with loose types, missing required markers, or no examples generate noisy tests and false failures — eroding trust in the whole suite. Solution: Treat spec quality as a precondition to regression automation. Run Spectral (or equivalent) as a blocking PR check on the spec itself, require examples on every schema, and enforce descriptions. The ROI on spec-quality tooling is higher than any other single investment in regression automation.
Environment drift masks regressions until late stages
Tests pass locally and in CI but fail in staging because of data, config, or timing assumptions that differ per environment — and by then the change has been merged. Solution: Use deterministic, freshly-generated test data per run. Run tests in a clean, isolated environment on every pipeline execution. Eliminate shared mutable state between tests. Run the same suite against staging as part of the deploy gate to catch environment-specific regressions before production.
Migrating from an existing Postman estate without stopping the world
Teams with thousands of collections cannot migrate overnight, and a rushed migration usually loses coverage. Solution: Run both in parallel during transition. Start AI-first regression on new endpoints only; migrate existing collections opportunistically as they require maintenance. See how to migrate from Postman to spec-driven testing and Postman alternative.
API regression testing best practices
- Run the full suite on every pull request. Selective testing saves time in the short term but misses side-effect regressions, which are precisely what regression testing exists to catch. If the full suite is too slow, parallelize — do not prune.
- Treat regression failures as hard merge blockers. A failing regression test means a real risk of production breakage. Never bypass a failing test to meet a deadline; the production incident will always cost more than the delay. Wire this as a policy-level branch protection rule, not a cultural norm.
- Generate from OpenAPI, then curate. Let a spec-driven platform author the baseline; use human effort for high-value business-logic tests the spec cannot express. Do not hand-write the core suite — that path does not scale. See generate tests from OpenAPI and OpenAPI test automation.
- Cover all three regression layers. Functional alone is insufficient. Contract regression catches schema drift; performance regression catches latency regressions. Most teams stop at functional and are surprised by incidents neither contract nor performance tests would have missed.
- Enforce coverage thresholds as quality gates. Set endpoint coverage and status-code coverage minimums in CI and block merges that reduce them. Track trends over time using API test coverage metrics.
- Measure and manage the regression escape rate. Escape rate is regressions found in production divided by all regressions found. Set a target against your own baseline (many teams aim for under 5%); a rising rate signals gaps in contract, negative-path or performance coverage. This is your north-star KPI.
- Keep false positives below 2%. If more than 2% of test failures are false positives (test issues, not real regressions), confidence evaporates and real failures get ignored. Treat FP rate as seriously as escape rate.
- Version tests with the application code. Store the regression suite in the same repository as the API implementation. When a developer modifies an endpoint, the tests are right there as a contract reminder, and PRs can change both atomically.
- Centralize environment and auth management. OAuth2 clients, JWT signers, API keys, and per-environment config live in the platform's vault — not scattered across CI environment variables. See integrations.
- Set a change-review policy deliberately. Auto-approve additive, non-breaking spec changes; require review on removed or changed required semantics. Tools that silently rewrite tests are worse than none because they mask real regressions.
- Invest in failure triage UX. Clear expected-vs-actual diffs, one-click local reproduction, readable assertion messages, and historical flakiness scoring matter more than generation sophistication. Developers adopt what is pleasant to debug.
- Review high-stakes flows manually on top of generation. Payments, auth, and compliance-sensitive endpoints get human-reviewed assertions layered on top of AI-generated baselines. AI covers breadth; humans cover depth where failure is unacceptable.
API regression testing checklist
- ✔ Inventory every API and locate its canonical OpenAPI spec
- ✔ Lint all specs with Spectral (or equivalent) as a blocking PR check
- ✔ Establish baseline regression coverage: endpoints, methods, status codes, auth schemes
- ✔ Select a pilot team and 10-20 APIs for initial onboarding
- ✔ Generate the regression suite from the spec using a spec-driven platform
- ✔ Author business-logic tests for scenarios the spec cannot express
- ✔ Add contract regression validating every response against the committed spec
- ✔ Add performance regression with P95 baselines for top-traffic endpoints
- ✔ Wire the full suite into CI (GitHub Actions, GitLab, Azure DevOps, Jenkins, or CircleCI)
- ✔ Configure PR-level merge blocks on any regression failure
- ✔ Configure deploy-level gates that run the suite against staging before production promotion
- ✔ Shard execution in parallel to keep PR feedback under five minutes
- ✔ Centralize auth (OAuth2, JWT, API keys) in the platform's vault
- ✔ Set a spec-change review policy: auto-approve non-breaking, review breaking
- ✔ Integrate failure notifications into Slack or Microsoft Teams
- ✔ Instrument KPIs: regression escape rate, false positive rate, flakiness, time-to-feedback
- ✔ Review and harden assertions on high-stakes flows (payments, auth, compliance)
- ✔ Retire overlapping Postman collections on a defined deprecation timeline
- ✔ Conduct quarterly review of regression ROI against DORA change-failure-rate benchmarks
Catch the regression before the tests even run
Most API regressions are contract regressions, and a spec diff finds those in seconds — before a single request is sent:
# fail the PR on any change that would break an existing consumer
git show origin/main:openapi.yaml > /tmp/base.yaml
oasdiff breaking /tmp/base.yaml openapi.yaml --fail-on ERR

# example output
# 1 breaking changes: 1 error, 0 warning
# error, in components/schemas/Order the property 'status' became required
Then run the behavioural regression suite, tagged so the fast set gates the PR and the full set runs nightly:
# tests/test_orders.py
import pytest

@pytest.mark.regression
@pytest.mark.parametrize("payload,expected", [
    ({"sku": "A-1", "qty": 1}, 201),
    ({"sku": "A-1", "qty": 0}, 422),      # boundary that regressed in 2.3.0
    ({"sku": "", "qty": 1}, 422),
])
def test_create_order_contract(client, payload, expected):
    assert client.post("/v1/orders", json=payload).status_code == expected

# pytest -m regression        -> PR gate (about 90 seconds)
# pytest -m "regression or slow" -> nightly full sweep
More from the API Testing in CI/CD hub
Every guide in this hub, grouped by format. The API Testing in CI/CD hub page has the full list.
Guides and concepts
- API Testing in GitHub Actions: Complete Workflow Guide (2026)
- What to Automate at Each CI/CD Stage: Tests and Gates
- Azure DevOps API Testing: Complete Pipeline Guide (2026)
- Why Postman Collections Are Not Enough for CI/CD Pipelines (2026)
How-to tutorials
- How to Debug Failed API Tests in CI/CD: Step-by-Step Guide (2026)
- How to Build Scalable API Test Reporting for QA Teams
- How to Run API Tests in Jenkins Pipelines
Tools and comparisons
API regression testing FAQ
What is API regression testing?
API regression testing is the practice of re-running existing API tests after every code change to verify that previously working functionality still works correctly. It catches unintended side effects — a fix in one endpoint breaking another, a schema change invalidating downstream consumers, or a performance degradation introduced by new code — before those regressions reach production. Regression testing typically runs automatically on every pull request and every merge to the main branch in a CI/CD pipeline.
How is API regression testing different from functional testing?
Functional testing verifies that an API endpoint satisfies a specific requirement at a single point in time. Regression testing re-runs those same functional tests — plus contract tests and performance baselines — continuously after every code change to ensure nothing broke. The tests may be identical; the difference is when and why they run. Functional testing validates new work; regression testing protects existing behavior as the codebase evolves.
How often should API regression tests run?
On every pull request, on every merge to main, and before every deployment to staging or production. The earlier a regression is caught, the closer it is to the change that caused it and the cheaper it is to fix. Run a fast set on pull requests and the full suite on merge, and gate both.
What are the best API regression testing tools?
It depends on who writes the tests. Code-first teams use REST Assured, Karate or pytest with requests; spec-driven teams add Schemathesis and an OpenAPI diff tool such as oasdiff; Postman teams run collections with Newman. Platforms such as Shift-Left API generate the suite from the OpenAPI spec and run it from CI with a pass-rate gate. The comparison table above covers the trade-offs.
How do you reduce regression test maintenance?
Generate the baseline from the spec and review changes as they arrive. In Shift-Left API a re-imported spec is diffed and each change is classified as breaking or non-breaking; approved changes become new endpoint versions and existing tests are not rewritten. When a test fails, AI repair proposes a fix that cites its evidence, for a person to accept.
How does API regression testing fit into CI/CD pipelines?
Regression tests run as automated quality gates at two points in the pipeline: a pull request gate that blocks merges on failure, and a deploy gate that blocks promotion to staging or production. Between those gates, tests run in parallel shards to keep feedback under five minutes, and failures surface as PR annotations and Slack or Teams alerts so developers can fix them before context is lost.
Sources and further reading
- OpenAPI Specification — the normative spec for describing HTTP APIs.
- oasdiff — breaking-change detection between two OpenAPI documents.
- Google Testing Blog — Google's engineering write-ups on test sizing and flakiness.
Key takeaways
- API regression testing is the automated safety net that lets modern engineering teams ship changes with confidence.
- Without it, every code change carries the risk of silently breaking existing functionality for the consumers — human, mobile, partner, and increasingly agentic — that depend on stable API contracts.
- With it, regressions become a CI-time event measured in minutes, not a production-time event measured in incidents and post-mortems.
- The playbook is clear. Build across three layers: functional regression for correctness, contract regression for spec compliance, performance regression for latency protection.
- Generate from OpenAPI rather than hand-authoring. Integrate into CI/CD with blocking quality gates at pull-request and deploy time.
- Invest in change detection and reviewed AI repair to keep maintenance sustainable as the API grows.
Measure regression escape rate and false positive rate as first-class KPIs. Retire the Postman-collection-as-regression-suite pattern; it does not scale past a few dozen endpoints.
The teams that catch regressions in CI — not in production — are the teams that ship faster, not slower, with lower change-failure rates and happier downstream consumers. To see this pattern running end-to-end — ingesting your OpenAPI spec, generating a comprehensive regression suite, running it in your CI pipeline, and proposing evidence-cited repairs for review when a test fails — explore the Shift-Left API platform, start a free trial, or book a live demo. First green regression run in under 10 minutes.
Related: API Testing in CI/CD | Smoke Testing vs Regression Testing | API Quality Gates | What Is API Contract Testing | API Schema Validation: Catching Drift | How Reviewed AI Repair Works | API Learning Center | Automated API Regression Testing | Start Free Trial
Ready to shift left with your API testing?
Import your OpenAPI spec and get a runnable test suite, in our cloud or on your own infrastructure.