
AI API Testing: How It Works, Use Cases and Tools
Quick answer
AI API testing uses AI to generate, run and triage API tests from a machine-readable contract such as OpenAPI, GraphQL or WSDL. The strongest tools plan coverage deterministically from the spec, use a language model for realistic data and extra edge cases, and propose repairs after a failure for a person to approve instead of rewriting tests silently.
Reviewed by Smeet Gohel
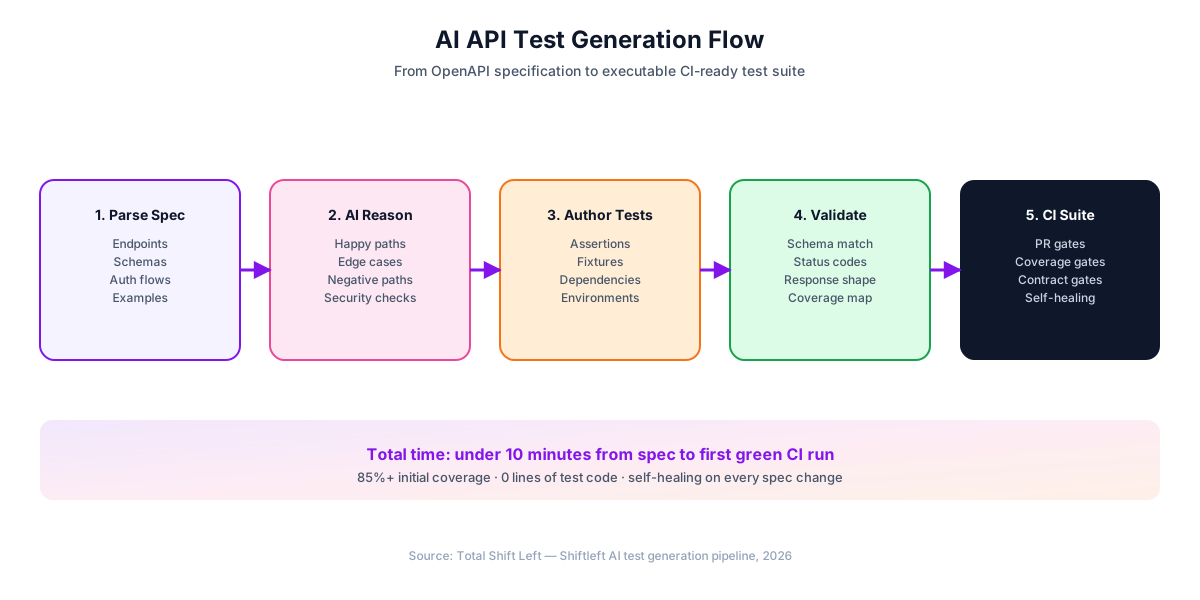
AI API testing is the use of AI to generate, run, maintain and triage API tests from a machine-readable contract: an OpenAPI or Swagger document, a GraphQL schema or a WSDL. Instead of an engineer scripting each request and assertion, the tool reads the contract, plans which tests should exist, builds them, runs them in CI and explains what broke. The engineer's job moves from authoring to reviewing. If you are evaluating a platform rather than learning the concept, the AI API testing platform page shows how we implement it.
This guide is the hub for everything we have written on the topic. It covers how generation actually works (and where a language model adds value versus where it does not), how failing tests get repaired without anyone losing control of the suite, an honest comparison with scripted API automation, concrete workflows you can run this quarter, the tool landscape and a 30-day adoption plan. Where a subject deserves its own article, we link to it.
One distinction runs through the whole piece. AI-assisted tools help a person write tests faster: a snippet, a suggested assertion, a chat panel inside a collection. AI-authored testing inverts that: the tool produces the suite and the person reviews it. Both are useful, but they change the cost of testing by very different amounts, and vendors blur them constantly.
In this guide
- What is AI API testing?
- How AI generates API tests
- How AI maintains and repairs API tests
- AI API testing vs traditional API automation
- AI API testing use cases and workflows
- AI API testing tools
- How to adopt AI API testing in 30 days
- AI API testing FAQ
- Sources and further reading
What is AI API testing?
API testing has always involved four jobs. AI API testing is the practice of handing the repetitive part of each job to a machine while a person keeps the judgment.
Authoring. The tool derives test cases from the contract: every operation and method, every documented response code, every parameter and every schema constraint. Good tools keep the output human-readable, so a reviewer can see what each test sends and asserts, and why it exists.
Running. Tests execute against a chosen environment in dependency order, with authentication handled per environment and data captured from one call (an order id, a token) passed into the next. In CI the run becomes a pass/fail gate on the pull request.
Maintaining. APIs change. A credible tool tells you what changed in the contract and holds it for review, and when a test later fails it proposes a repair with the evidence behind it. Nothing rewrites tests behind your back.
Triaging. When a run goes red, the tool groups failures by likely cause (test defect, data problem, environment problem, possible product bug, flake) so an engineer starts from three causes instead of forty stack traces.
A platform that covers all four is doing AI API testing. A tool that does one of them inside a manual workflow, such as suggesting assertions while you hand-build a collection, is AI-assisted. Codeless builders sit between the two; how to automate API testing without writing code maps where they fit.
AI API testing vs testing AI APIs
The phrase is used for two different problems, and search results mix them freely.
- Using AI to test ordinary APIs. A REST, GraphQL or SOAP service with deterministic behaviour, tested with tests that AI helped produce. That is most of this guide.
- Testing APIs that are themselves AI. An endpoint backed by a language model, a retrieval pipeline or an agent, where the same request can produce different valid answers. Equality assertions stop working, and you need invariants, rubric scoring and eval sets. Start with how to test LLM applications, then building an LLM eval suite that catches regressions.
A third case sits between them: Model Context Protocol servers, which expose tools for agents over JSON-RPC. They are deterministic APIs with an AI-shaped client, and they need handshake, tool-schema and prompt-injection cases. See how to test MCP servers and MCP vs REST APIs for testers.
How AI generates API tests
Generation is where marketing claims are loudest and where the engineering differences matter most.
Prompt-first vs plan-first engines
Generators come in two shapes.
- Prompt-first. The tool sends the spec (or a slice of it) to a language model and keeps what comes back. Fast to build, but the output depends on the prompt and the model's mood: run it twice and you get two different suites, and nothing tells you which scenario a test was meant to cover or which ones are missing.
- Plan-first. The tool works out, from the spec alone, which tests should exist for each endpoint, builds those deterministically, and only then lets a model improve them. Every test traces back to a named scenario, generating twice gives the same suite, and coverage can be measured against the plan.
Plan-first is easier to review and easier to trust in a gate. It is also the only shape that still works when policy forbids sending specs to a model provider.
Three kinds of reasoning
Whichever shape a tool uses, three kinds of reasoning have to happen:
Semantic understanding. Reading endpoint names, descriptions and examples to infer intent: telling POST /orders (create) from POST /orders/{id}/cancel (a state transition), and choosing a plausible email, currency code or postcode instead of random bytes. This is where a language model earns its place.
Constraint and boundary reasoning. Turning JSON Schema keywords such as minimum, maximum, maxLength, pattern, enum and required into cases: the smallest and largest valid values, one step past each limit, a string that breaks the pattern, a missing required field, a value of the wrong type. None of this needs a model. Property-based tools like Schemathesis have derived these cases from schemas for years.
Assertion inference. Rather than hard-coding "expect 200", converting the contract into checks: required response fields become existence assertions, format: date-time becomes a parse check, enums become membership checks, and declared 4xx responses become negative-path expectations.
The output is a candidate set of positive, negative, boundary and authentication tests that a person reviews before it gates anything. The step-by-step mechanics, with examples per schema keyword, are in how to generate API tests from OpenAPI with AI.
A worked example: one endpoint, planned
Take a single operation:
/orders:
  post:
    security: [{ bearerAuth: [] }]
    requestBody:
      required: true
      content:
        application/json:
          schema:
            type: object
            required: [sku, qty]
            properties:
              sku: { type: string, pattern: '^[A-Z]-\d+$' }
              qty: { type: integer, minimum: 1, maximum: 100 }
    responses:
      '201': { description: Created }
      '400': { description: Validation error }
      '401': { description: Unauthorized }
A plan-first engine derives, before any model is involved: a valid create that expects 201 and the declared response fields; qty at 1 and 100 (valid) and at 0 and 101 (expect 400); a sku that breaks the pattern; each required field missing in turn; qty sent as a string; a request with no token and one with a malformed token (expect 401); and, if security probes are enabled, injection-style inputs that only detect, never exploit. A model can then rename the tests readably, replace "A-1" with SKUs that look like your catalogue, and suggest an edge case the schema hints at but does not state, such as duplicate submission of the same order.
Generation without an AI key
Shift-Left API is a plan-first engine. Its coverage engine plans 79 scenario classes across 12 test dimensions (functional, field validation, boundary, equivalence, HTTP semantics, authentication, authorization, idempotency, performance, business rules and security among them), including 13 authentication-bypass checks and 33 security probes, and builds one test per planned intent with no language model involved. A team with no AI key, or one that is not allowed to send specs to a provider, still gets a full structured suite. Security and performance probes can be switched on or off per project.
When an AI key is configured, AI is layered on top in two bounded steps: it polishes names and swaps synthetic values for realistic ones on positive tests, and it adds at most 8 extra edge-case tests per endpoint. It never removes or weakens a planned test, and if the provider errors, the deterministic suite stands. The model can come from any of 19 provider families with your own key, or from a self-hosted model on Ollama, LM Studio or vLLM on the Trial and Enterprise plans. Generating again later matches tests by their planned intent, so existing tests are kept with their run history and only missing ones are added.
Ready to shift left with your API testing?
Try our no-code API test automation platform free. Generate tests from OpenAPI, run in CI/CD, and scale quality.
Input does not have to be a spec alone. Requirement documents and user stories (from Jira, Azure DevOps, Gherkin or plain text) feed business-rule scenarios, so each test can trace back to the requirement it checks. For keeping generation entirely inside your network, read running AI test generation on your own LLM and, for disconnected environments, air-gapped API testing patterns.
How AI maintains and repairs API tests
Maintenance is where "AI testing" claims vary most, so precise language helps. Three things are often bundled under one buzzword: noticing that the contract changed, fixing a test that failed, and doing either without a human. Treat them separately.
Spec change detection
When an updated spec is imported, a good tool diffs it against the previous version and classifies each change: an added optional field or a new endpoint is non-breaking; a removed field, a narrowed type, a new required parameter or a changed status code is breaking. The diff is shown for review with an approve or reject decision, and approved changes become new versions of the affected endpoints with history kept. Some teams let non-breaking changes approve automatically.
What should not happen is a tool quietly editing test assertions because the spec moved. If the contract changed and the implementation did not, a rewritten test hides the drift you most needed to see. Change detection and contract testing work together here; API contract testing covers the consumer and provider sides.
Repair after a failure
Repair belongs after a test fails, not before. The useful pattern looks like this:
- The tool reads the failing test, its last run, the relevant part of the spec and any linked requirement.
- It classifies the failure: test defect, data issue, possible product bug, environment issue or flaky.
- For test defects and data issues it proposes a patch with a confidence score and a before/after diff. For a suspected product bug or an environment problem it proposes nothing, because "fixing" the test would hide a real defect.
- A person applies the patch, edits it first, or discards it.
Guards matter more than cleverness. In Shift-Left API, a negative test is never loosened into one that always passes, the endpoint path is never changed, and every proposal has to cite its evidence. For a red run with many failures, run triage groups them into a few causes and proposes one fix per cause for review. An automatic repair loop exists, but it is off until a project opts in, it only triggers after two consecutive failures, and it creates suggestions unless auto-apply is also switched on.
The industry has a buzzword for this broader idea. It is worth reading how self-healing API tests work for the vendor-neutral mechanics and the failure modes, then asking any vendor exactly what happens to a test when the spec changes and nobody is watching.
AI API testing vs traditional API automation
Traditional API automation means a person authors each test: REST Assured or pytest code, Postman collections run through Newman, Karate feature files, or a codeless builder such as ReadyAPI or Katalon. It is mature and flexible. Its cost grows with every endpoint, and coverage tends to decay because the API evolves faster than anyone has time to keep the tests current.
AI API testing changes where the work goes rather than removing it. Authoring cost per endpoint drops close to zero; review, spec hygiene and gate policy become the real work.
| Dimension | Traditional API automation | AI API testing |
|---|---|---|
| Who writes the tests | Engineers, one test at a time | The tool, from the spec and requirements; engineers review |
| What bounds coverage | Hours available to script | Quality and completeness of the spec |
| Negative and boundary cases | Whatever the author thought of | Derived systematically from every schema constraint |
| When the API changes | Someone diffs the spec and edits tests by hand | Change is classified at import and held for approval |
| When a test fails | Engineer reads logs and patches the test | Failure is classified; a patch is proposed with evidence for review |
| Contract checks | Extra plugin or hand-written schema checks | Built into generated assertions |
| Protocols | Often one tool per protocol | One engine across REST, GraphQL and SOAP in most platforms |
| Ownership of test logic | Code a person maintains forever | A plan you review; generated tests are readable and editable |
The same test, two ways
The difference is not the assertion; it is who carries the contract. Hand-written automation duplicates the contract inside the test file, so every spec change is a code change:
def test_create_order(client):  # traditional: the contract lives in the test
    r = client.post("/orders", json={"sku": "A-1", "qty": 2})
    assert r.status_code == 201
    body = r.json()
    assert {"id", "sku", "qty", "status"} <= set(body)
    assert body["status"] == "pending"
Spec-driven generation keeps the contract in the OpenAPI document and derives the cases from it, so a spec change becomes a diff to review instead of a pile of broken files:
schemathesis run openapi.yaml \
  --url https://staging.example.com \
  --checks all \
  --report junit --report-junit-path results.xml
When to use which
Choose AI API testing when:
- You have dozens or hundreds of endpoints and specs that change weekly.
- Negative, boundary and authorization coverage is thin because nobody has time to script it.
- Several protocols (REST plus some SOAP or GraphQL) currently need several tools.
- The QA team spends more time fixing broken assertions than testing new behaviour.
Keep hand-written automation when:
- The API is small, stable and unlikely to grow.
- The behaviour you need to check is not describable in the spec: complex multi-service business invariants, financial calculations, timing-dependent flows.
- Policy requires every line of test logic to be authored and owned by a named engineer.
- There is no spec and no realistic way to produce one.
Most teams end up with both: generated suites for breadth on every PR, a small hand-written or workflow-based set for the critical cross-service journeys. Existing collections are rarely wasted: most platforms import them, typically as one test per request with assertions, variable captures and auth settings carried over, plus a list of anything that could not be converted. Run old and new side by side for a few weeks before retiring anything, and judge the result against your own baseline: coverage of the spec, weekly maintenance hours, and regressions that escaped to staging.
AI API testing use cases and workflows
"Automate API testing with AI" can mean anything from a suggested assertion to an owned end-to-end loop. These workflows are the ones teams actually run, roughly in the order worth adopting them.
- Spec-to-suite generation. Import a spec by file, URL or a pasted cURL command and get a reviewed suite covering happy paths, validation errors, boundaries and auth. This is the easiest win to validate, so start here.
- Regression on every pull request. The full suite runs as a pipeline step; the quality gate fails the build below a pass-rate threshold or on any errored test. The regression-specific playbook is in the API regression testing guide.
- Contract validation. Generated tests assert the fields, types and status codes the spec declares, so implementation drift shows up as a failing check rather than a consumer incident.
- Breaking-change review. A new spec version is diffed and classified before it is accepted, so a removed field or a new required parameter gets a human decision instead of surprising consumers.
- Coverage gap filling. A coverage view shows untested status codes, parameters, body fields and planned scenarios per endpoint; filling a gap is a one-click generation, not a ticket. Our free OpenAPI coverage scorer gives a quick read of how testable your spec is before you start.
- Authentication flows. OAuth 2.0, JWT, API keys, mTLS and multi-step sign-in are configured once per environment and applied to every generated test, including the negative cases (no token, expired token, wrong scope).
- Data-driven variants. Positive tests are fed from realistic values, fixtures or a data source, so the same test runs across many rows without being copied.
- Repair after an intentional change. When a deliberate behaviour change makes tests fail, AI proposes updated assertions or request bodies as a reviewable diff instead of leaving forty red tests to fix by hand.
- Run triage. A failed run is grouped into a handful of causes with a verdict each, and green runs are checked too, for tests that passed without asserting what the requirement needed.
- Mocks for unstable dependencies. Mocks generated from the spec's examples and schemas let consumers be tested while an upstream is flaky or unfinished.
- Stakeholder reporting. Coverage and failure trends per service roll up for QA and engineering leads, so test health is discussed with data, not anecdotes.
Free ZIP: guide + approval checklist CSV
AI-Policy-Safe API Testing: Self-Hosted LLM Evaluation Kit
Evaluate self-hosted LLM test generation: map data flows, compare Ollama, vLLM and LM Studio, and get AI-policy approval with a 26-control checklist.
Download FreeAutomate one workflow at a time and let it stabilise for a couple of weeks before adding the next. Teams that switch everything on at once usually end up switching half of it off again.
For CI-specific wiring see API test automation in CI/CD, step by step. If your codebase is increasingly written by assistants, testing AI-generated code covers the gates that hold up, and the future of software testing in AI-driven development takes the longer view.
AI API testing tools
The landscape splits into three groups by what the AI actually does.
AI-authored API testing platforms. Spec-driven generation, change detection, repair proposals, CI gating, triage and governance in one product. The test suite is the product's output; you review and steer it.
AI-assisted tools. Collection-based clients with an AI helper, IDE coding assistants, codeless builders with AI-suggested assertions. They speed up per-test authoring but leave the labour model unchanged: a person still owns every test.
Agentic tools. An agent decides what to explore at run time rather than executing a planned suite. Promising for exploratory coverage, harder to put in a deterministic gate. Agentic QA tools covers the landscape and the four questions worth asking any vendor.
| Tool | What the AI does | Input it needs | Runs in CI | Open source | Best for |
|---|---|---|---|---|---|
| Schemathesis | Derives positive, negative and boundary cases from the schema (property-based, no LLM) | OpenAPI / GraphQL | Yes | Yes | The free baseline any AI tool should beat |
| Shift-Left API | Plans and generates the suite from the spec and requirements, holds spec changes for approval, tracks coverage, groups failed runs into causes and proposes fixes | OpenAPI, WSDL, GraphQL, requirement documents | Yes | No | Teams that want the suite maintained, not just generated |
| Postman (Postbot) | Suggests assertions and test scripts inside a collection | Saved requests | Via Newman or the Postman CLI | No | Teams already living in collections |
| Keploy | Records real traffic and converts it into test cases and mocks | Live traffic | Yes | Yes | APIs with no spec but plenty of traffic |
| Akto | Generates security test cases per endpoint | Traffic or spec | Yes | Partly | API security coverage specifically |
| IDE coding assistants | Draft test code a person reviews and owns | Your source code | No | No | Speeding up hand-written suites |
The dividing line worth noticing: tools near the top produce a suite you review and steer; tools near the bottom produce a first draft you maintain forever. For a broader ranked list across UI, mobile and API testing, see the best AI testing tools.
When you evaluate, run each candidate against the same real spec and ask:
- Is generation repeatable? Run it twice and diff the suites.
- Can you see which scenario each test covers, and which planned scenarios are missing?
- What happens to tests when the spec changes and nobody is watching?
- Will a repair ever weaken a negative test or patch over a product bug?
- Does it work with no AI key, or with a self-hosted model, if policy requires it?
- How does it gate CI, and which CI systems are first-party versus driven through an API?
How to adopt AI API testing in 30 days
The rollout fails in predictable places. Plan for them.
Challenges to expect
The spec does not match the implementation. The first generated run nearly always exposes drift: undocumented fields, wrong status codes, missing error responses. Treat the cleanup as a deliverable, not a blocker; better documentation is a side effect your consumers will thank you for.
Authentication blocks onboarding. OAuth 2.0 flows, mTLS, token rotation and custom sign-in are the most common reason a service stalls. Configure auth per environment before generating, and verify a single authenticated call first.
The gate is too strict too early. A 95% pass-rate gate on day one turns into a wall people learn to bypass. Start around 80%, hold it for two weeks, then raise it.
Nobody owns breaking-change decisions. Decide early which APIs are externally consumed and who approves breaking changes for each.
Generated tests are mistaken for end-to-end coverage. Generation excels at breadth per endpoint. Cross-service journeys (sign up, order, pay, refund) still need a small set of workflows; some platforms can build those from use-case requirements and wire each step's data to the step that produced it.
Practices that pay off
- Treat the spec as code. Lint it, version it and review it in pull requests. Spec quality sets the ceiling on test quality.
- Start with the most painful service, not the easiest: the one with frequent regressions or the highest change rate. The story from week one sets the pace of the rollout.
- Onboard service by service. It builds advocates and avoids change-management drag.
- Feed triage into postmortems. When a regression escapes, include the tool's cause analysis; patterns show up quickly.
- Keep exploration tools. A request client stays useful for design and ad-hoc debugging even when automation moves elsewhere.
A 30-day plan
- Days 1-3. Pick one service with real pain. Record a baseline: tests, spec coverage, weekly maintenance hours, escaped regressions.
- Days 4-7. Import the spec, configure auth, generate the suite and review it with the service owner.
- Days 8-14. Run against a preview or staging environment on every PR without gating. Tune environments, data and auth.
- Days 15-21. Turn on the gate at a lenient threshold. Watch the first ten runs and triage every failure.
- Days 22-25. Write down the breaking-change policy and assign approvers.
- Days 26-30. Onboard two or three more services, compare against the baseline, and plan the next 60 days.
You can wire the open-source baseline into CI today, before choosing a platform, so you have something to compare against:
Save this as .github/workflows/api-tests.yml:
name: API tests
on: [pull_request]
jobs:
  contract:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with: { python-version: '3.12' }
      - run: pip install schemathesis
      - run: schemathesis run openapi.yaml --url ${{ secrets.STAGING_URL }} --checks all
Key takeaways
- AI API testing moves the bottleneck from writing tests to spec quality, review and gate policy.
- Prefer plan-first generation: repeatable, traceable to scenarios, and usable with no AI key.
- Keep spec change detection and test repair separate, and insist that repairs are proposed after a failure and approved by a person.
- Use generated suites for breadth on every PR and a small set of workflows for critical journeys.
If you want to see plan-first generation, change review and run triage on one of your own specs, book a demo and bring the spec.
AI API testing FAQ
What is AI API testing?
AI API testing is the use of AI to generate, run, maintain and triage API tests from a machine-readable contract such as an OpenAPI, GraphQL or WSDL definition. The tool authors the first version of the suite and explains failures; an engineer reviews the tests, sets the quality gate and approves any repair before it lands.
How do you automate API testing with AI?
Start from a clean spec, configure authentication per environment, generate a suite for one service, review it, then run it as a pipeline step that gates pull requests on pass rate. Add AI repair proposals and run-level failure triage once the gate is trusted, and onboard further services one at a time.
Can AI generate API test cases from an OpenAPI spec?
Yes. The spec gives every operation, parameter, schema constraint and documented response, which is enough to derive positive, negative, boundary and authentication cases. Much of that needs no model at all; a language model adds realistic values and edge cases that the schema alone does not reveal. See how to generate API tests from OpenAPI with AI.
Is AI-based API testing better than traditional API automation?
For teams with many endpoints and frequent spec changes it usually is, because coverage tracks the spec instead of the hours available to script it. Hand-written suites still win for a handful of stable endpoints, for logic the spec cannot describe, and where every line of test code must be owned by a person.
Does AI API testing require sending my spec to an AI provider?
Not necessarily. Plan-first engines build the core suite deterministically with no model, and some tools let you bring your own key or point generation at a self-hosted model on Ollama, LM Studio or vLLM so that specs never leave your network.
How is AI used in API automation testing in CI/CD?
The generated suite runs as a CI step on every pull request and fails the build when the pass rate drops below a threshold, with JUnit results in the CI test tab. AI then groups the failures of a red run into causes and proposes fixes that a reviewer accepts or discards.
Sources and further reading
- OpenAPI Specification — the normative spec for describing HTTP APIs.
- JSON Schema — the constraint vocabulary that boundary and validation cases are derived from.
- GraphQL specification — the schema language behind GraphQL test generation.
- Schemathesis documentation — property-based testing driven straight from an OpenAPI or GraphQL schema.
- OWASP API Security Top 10 — the risk list that authorization and security probes map to.
- OWASP Top 10 for LLM Applications — the risk list for AI-backed endpoints.
- Model Context Protocol specification — the protocol behind MCP servers.
Continue learning
Go deeper in the Learning Center
Hands-on lessons with runnable code against our live sandbox.
Ready to shift left with your API testing?
Import your OpenAPI spec and get a runnable test suite, in our cloud or on your own infrastructure.